

Share Latest Apr-2026 CKADTest Practice Test Questions, Exam Dumps
Positive Aspects of Valid Dumps CKAD Exam Dumps!
NEW QUESTION # 26
You are tasked With deploying a new web application on Kubernetes. The application is designed to be highly available and requires persistent storage for user dat a. The application needs to be able to handle incoming requests even during rolling updates. How would you design the deployment using StatetulSets, ensuring that the application remains available and data is preserved even when updating the deployment?
Answer:
Explanation:
See the solution below with Step by Step Explanation.
Explanation:
Solution (Step by Step) :
I). Create a PersistentVoIumeCIaim:
- Define a PersistentVoIumeCIaim (PVC) to request the necessary storage space for the application's data. This ensures persistent storage is provisioned for each pod.
2. Define a StatefulSet: - Create a StatefulSet that defines the deployment configuration. Ensure that the following configurations are included: - 'serviceName': Define a service name for the StatefulSet. - 'replicas': Define tne number of replicas (pods) required for the application. - 'volumeClaimTemplates': Include the previously defined PVC to ensure each pod is assigned persistent storage. - 'template-spec-containers. volumeMounts': Mount the volume from the PVC at the desired location within the container. - 'podManagementP01icy: Parallels: Configure the podManagementP01icy to allow parallel pod updates during rolling updates, maintaining application availability.
3. Create the Service. - Create a service that exposes the application to the outside world Use the 'ClusterlP' service type for internal access within the Kubernetes cluster.
4. Apply the Configuration: - Apply the StatefulSet, PVC, and service configurations using 'kubectl apply -f' to deploy the application on Kubernetes. 5. Verify the Deployment: - Use 'kubectl get statefulsets webapp-statefulset and 'kubectl get pods -I app=webapp' to verify that the StatefuISet has been deployed successfully and the pods are running with the correct configurations. 6. Test Rolling Updates: - Push a new image to the 'example/webapp:latest Docker Hub repository. The StatetulSet will automatically initiate a rolling update. Monitor the pods using 'kubectl get pods -l app=webapp' to observe the update process. You should see that pods are updated one at a time, ensuring that the application remains available throughout the update. Important Notes: - StatetulSets are ideal for applications that require persistent storage, unique identifiers, and ordered deployments, making them suitable for highly available web applications. - The 'podManagementPolicy: Parallel' setting ensures that the application remains available even when pods are updated. - Always define a 'partition' in the 'rollinglJPdate' strategy to ensure that all pods are part of the update. - Consider using liveness probes and readiness probes Within your application containers for health checks to ensure the application is healthy during the rolling update process. - For external access, you can use a LoadBalancer service type in the service definition.,
NEW QUESTION # 27
You must connect to the correct host . Failure to do so may result in a zero score.
[candidate@base] $ ssh ckad00033
Task
A Dockerfile has been prepared at /home/candidate/build/Dockerfile.
Using the prepared Dockerfile, build a container image with the name macaque and tag 1.2. You may install and use the tool of your choice.
Multiple image builders and tools have been pre-installed in the base system, including: docker, skopeo, buildah, img , and podman.
Please do not push the built image to a registry, run a container, or otherwise consume it.
Using the tool of your choice, export the built container image in OCI or Docker image format and store it at
/home/candidate/macaque-1.2.tar.
Answer:
Explanation:
See the Explanation below for complete solution.
Explanation:
Understood - I'll redo Question 13 without using any # (or similar) icons.
ssh ckad00033
This task is only about building and exporting a container image.
You must not push it, run it, or consume it in any way.
You may use any image builder. Below are clean, correct solutions. Use one of them.
Option A: Using Docker
1) Go to the Dockerfile location
cd /home/candidate/build
ls -l Dockerfile
2) Build the image
Image name: macaque
Tag: 1.2
docker build -t macaque:1.2 .
Verify:
docker images | grep macaque
3) Export the image to a tar file
Docker image format is acceptable.
docker save macaque:1.2 -o /home/candidate/macaque-1.2.tar
Verify the file exists:
ls -lh /home/candidate/macaque-1.2.tar
Do not load or run the image.
Option B: Using Podman (rootless alternative)
1) Build the image
cd /home/candidate/build
podman build -t macaque:1.2 .
Verify:
podman images | grep macaque
2) Export the image
podman save macaque:1.2 -o /home/candidate/macaque-1.2.tar
Verify:
ls -lh /home/candidate/macaque-1.2.tar
Option C: Using Buildah (OCI format)
cd /home/candidate/build
buildah bud -t macaque:1.2 .
buildah push macaque:1.2 oci-archive:/home/candidate/macaque-1.2.tar
NEW QUESTION # 28 
Context
A user has reported an aopticauon is unteachable due to a failing livenessProbe .
Task
Perform the following tasks:
* Find the broken pod and store its name and namespace to /opt/KDOB00401/broken.txt in the format: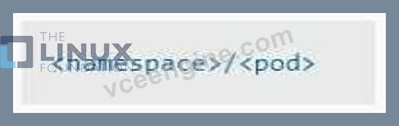
The output file has already been created
* Store the associated error events to a file /opt/KDOB00401/error.txt, The output file has already been created. You will need to use the -o wide output specifier with your command
* Fix the issue.
Answer:
Explanation:
See the solution below.
Explanation
Solution:
Create the Pod:
kubectl create
-f http://k8s.io/docs/tasks/configure-pod-container/
exec-liveness.yaml
Within 30 seconds, view the Pod events:
kubectl describe pod liveness-exec
The output indicates that no liveness probes have failed yet:
FirstSeen LastSeen Count From SubobjectPath Type Reason Message
--------- -------- ----- ---- ------------- -------- ------ -------
24s 24s 1 {default-scheduler } Normal Scheduled Successfully assigned liveness-exec to worker0
23s 23s 1 {kubelet worker0} spec.containers{liveness} Normal Pulling pulling image
"gcr.io/google_containers/busybox"
23s 23s 1 {kubelet worker0} spec.containers{liveness} Normal Pulled Successfully pulled image
"gcr.io/google_containers/busybox"
23s 23s 1 {kubelet worker0} spec.containers{liveness} Normal Created Created container with docker id
86849c15382e; Security:[seccomp=unconfined]
23s 23s 1 {kubelet worker0} spec.containers{liveness} Normal Started Started container with docker id
86849c15382e
After 35 seconds, view the Pod events again:
kubectl describe pod liveness-exec
At the bottom of the output, there are messages indicating that the liveness probes have failed, and the containers have been killed and recreated.
FirstSeen LastSeen Count From SubobjectPath Type Reason Message
--------- -------- ----- ---- -------------
37s 37s 1 {default-scheduler } Normal Scheduled Successfully assigned liveness-exec to worker0
36s 36s 1 {kubelet worker0} spec.containers{liveness} Normal Pulling pulling image
"gcr.io/google_containers/busybox"
36s 36s 1 {kubelet worker0} spec.containers{liveness} Normal Pulled Successfully pulled image
"gcr.io/google_containers/busybox"
36s 36s 1 {kubelet worker0} spec.containers{liveness} Normal Created Created container with docker id
86849c15382e; Security:[seccomp=unconfined]
36s 36s 1 {kubelet worker0} spec.containers{liveness} Normal Started Started container with docker id
86849c15382e
2s 2s 1 {kubelet worker0} spec.containers{liveness} Warning Unhealthy Liveness probe failed: cat: can't open
'/tmp/healthy': No such file or directory
Wait another 30 seconds, and verify that the Container has been restarted:
kubectl get pod liveness-exec
The output shows that RESTARTS has been incremented:
NAME READY STATUS RESTARTS AGE
liveness-exec 1/1 Running 1 m
NEW QUESTION # 29
You are running a web application on Kubernetes, and you need to schedule a daily backup of your application's dat a. The backup process involves running a script that archives the database and uploads it to a remote storage service. Explain how you would implement this using a CronJ0b in Kubernetes. Provide a sample YAML configuration for the Cronjob.
Answer:
Explanation:
See the solution below with Step by Step Explanation.
Explanation:
Solution (Step by Step) :
1. Create a Container Image:
- Create a Dockerfile that packages the backup script and any necessary dependencies into a container image-
- Build tne image and push it to a container registry (e.g., Docker Hub).
dockefflle
FROM ubuntu:latest
# Install necessary packages
RUN apt-get update && apt-get install -y zip
# Copy the backup script to the container
COPY backup.sh 'backup.sh
# Set entrypoint to the backup script
ENTRYPOINT ["/backup.sh"]
2. Create the CronJob YAML:
- Define the 'cronJob' resource in a YAML file. Specify the schedule, the container image, and the command to run.
3. Apply the CronJob: - Apply the YAML file to your Kubernetes cluster using 'kubectl apply -f cronjob.yamr 4. Verification: - Use 'kubectl get cronjobs' to check if the CronJob was successfully created- - Check the Kubernetes logs for the CronJob to ensure it's running as expected.
NEW QUESTION # 30
You are building a microservice application that consists of multiple Pods. Each Pod needs to access a shared database hosted in a separate Pod. How would you create a ConfigMap to store the database connection details and make it available to all Pods in the application?
Answer:
Explanation:
See the solution below with Step by Step Explanation.
Explanation:
Solution (Step by Step) :
I). Create a ConfigMap:
- Create a ConfigMap named "database-config' to store the database connection details.
- Replace 'your-database-hostname' , 'your-database-port, 'your-database-user, and 'your-database-password' with the actual connection information.
2. Mount the ConfigMap to Pods: - In tne Deployment configurations for each microservice Pod, mount the 'database-config' ConfigMap as a volume. - Use 'envFror-n' to include the ConfigMap's data as environment variables for the application container - This way, the application can access the database connection details directly through environment variables.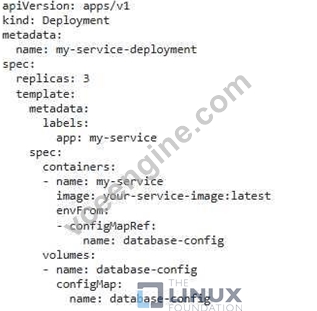
3. Verify the Connection: - Once the Pods are deployed, you can check the application logs to ensure that they are successfully connecting to the database using the provided connection details.
NEW QUESTION # 31
You are deploying a new application named 'streaming-services that requires 7 replicas. You want to implement a rolling update strategy that allows for a maximum of two pods to be unavailable at any given time. However, you need to ensure that the update process is triggered automatically whenever a new image is pusned to the Docker Hub repository 'streaming/streaming-service:latest'.
Answer:
Explanation:
See the solution below with Step by Step Explanation.
Explanation:
Solution (Step by Step) :
I). Update the Deployment YAMI-:
- Update the 'replicas' to 7.
- Define 'maxunavailable: 2" and 'maxSurge: (Y in the 'strategy.rollingUpdate' section.
- Configure a 'strategy.types to 'Rollingl_lpdates to trigger a rolling update when the deployment is updated.
- Add a 'spec-template.spec.imagePullPolicy: Always' to ensure that the new image is pulled even if it exists in the pod's local cache.
2. Create the Deployment: - Apply the updated YAML file using 'kubectl apply -f streaming-service-deployment-yamr 3. Verify the Deployment - Check the status of the deployment using 'kubectl get deployments streaming-service-deployment to confirm the rollout and updated replica count. 4. Trigger the Automatic Update: - Push a new image to the 'streaming/streaming-service:latest' Docker Hub repository. 5. Monitor the Deployment - Use 'kubectl get pods -l app=streaming-service' to monitor the pod updates during the rolling update process. You will observe that two pods are terminated at a time, while two new with the updated image are created. 6. Check for Successful Update: - Once the deployment is complete, use 'kubectl describe deployment streaming-service-deployment' to see that the 'updatedReplicas' field matches the 'replicas' field, indicating a successful update.
NEW QUESTION # 32 
Given a container that writes a log file in format A and a container that converts log files from format A to format B, create a deployment that runs both containers such that the log files from the first container are converted by the second container, emitting logs in format B.
Task:
* Create a deployment named deployment-xyz in the default namespace, that:
*Includes a primary
lfccncf/busybox:1 container, named logger-dev
*includes a sidecar Ifccncf/fluentd:v0.12 container, named adapter-zen
*Mounts a shared volume /tmp/log on both containers, which does not persist when the pod is deleted
*Instructs the logger-dev
container to run the command
which should output logs to /tmp/log/input.log in plain text format, with example values:
* The adapter-zen sidecar container should read /tmp/log/input.log and output the data to /tmp/log/output.* in Fluentd JSON format. Note that no knowledge of Fluentd is required to complete this task: all you will need to achieve this is to create the ConfigMap from the spec file provided at /opt/KDMC00102/fluentd-configma p.yaml , and mount that ConfigMap to /fluentd/etc in the adapter-zen sidecar container See the solution below.
Answer:
Explanation:
Solution: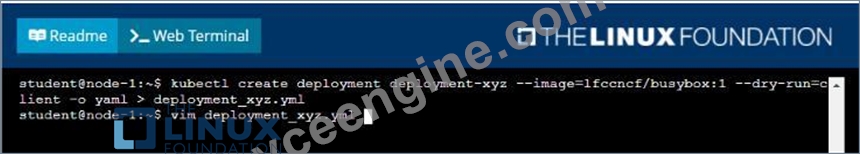


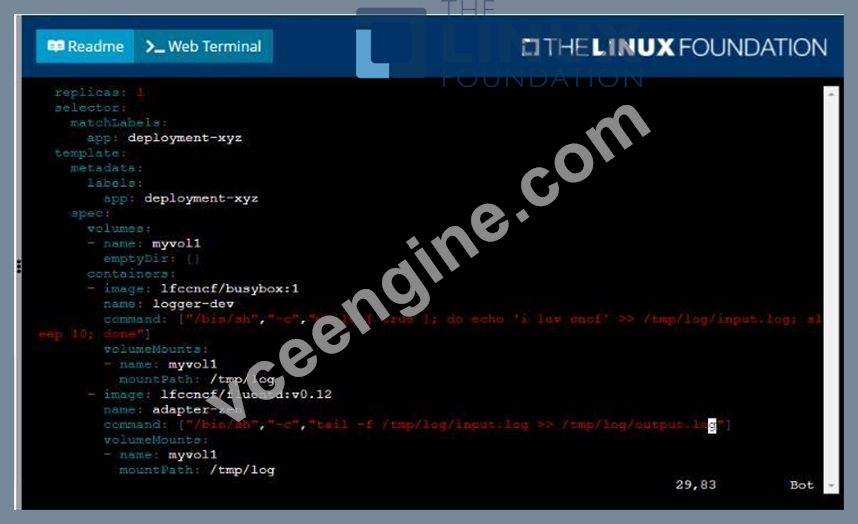
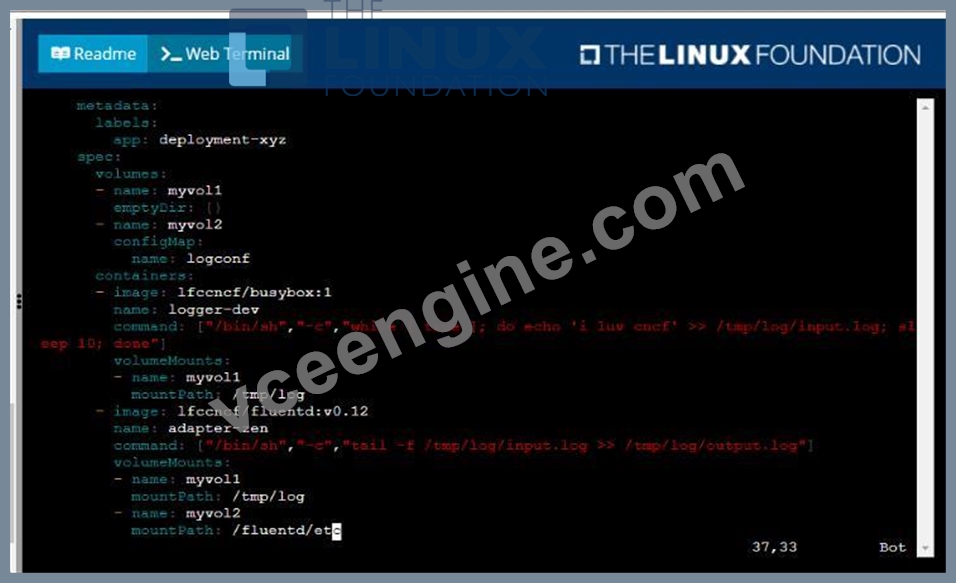
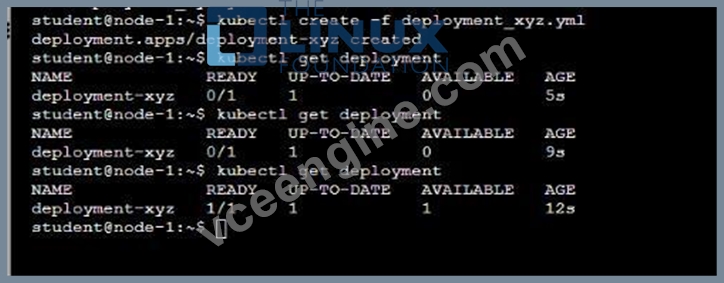
NEW QUESTION # 33
You are building a container image for a Spring Boot application that connects to a MySQL database. The application requires specific environment variables, such as the database nostname, username, password, and port. How would you define these environment variables Within the Docker-file to ensure the application runs correctly in a Kubernetes cluster?
Answer:
Explanation:
See the solution below with Step by Step Explanation.
Explanation:
1. Define Environment Variables in Docker-file:
- Utilize the 'ENV' instruction within your Dockerfile to set the necessary environment variables.
- These variables will be accessible to your Spring Boot application during runtime.
- Example:
dockerfile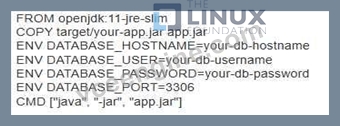
2. Build the Docker Image: - Construct your Docker image using the Docker-file. - Run the following command: 'docker build -t your-image-name 3. Deploy to Kubernetes: - Create a Deployment or Pod in Kubernetes that utilizes your built image. - Ensure the pod's environment variables align with the ones defined in your Dockerfile. - Example (Deployment YAML):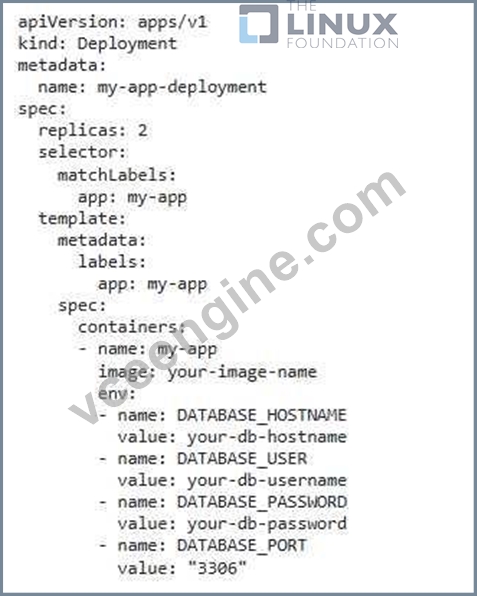
4. Verify Application Functionality: - Access your deployed application in the Kubernetes cluster. - Verify that it connects successfully to the database and operates as expected.
NEW QUESTION # 34
You have a Deployment that runs a critical service with 5 replicas. You need to update the service with a new image, but you want to ensure that only one replica is unavailable at a time during the update process. You also want to control how long the update process can take. How would you implement this using the 'rollinglJpdate' strategy?
Answer:
Explanation:
See the solution below with Step by Step Explanation.
Explanation:
Solution (Step by Step) :
1. Update the Deployment YAMLI
- Set 'strategy.type' to 'RollingLJpdate'
- Configure 'strategy.rollingupdate.maxunavailable' to 'I' to limit the number of unavailable replicas during the update.
- Set 'strategy-rollinglJpdate.maxSurge' to to allow for a maximum of six replicas during the update process.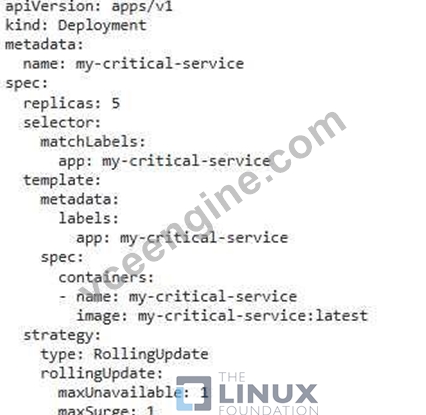
2. Control Update Duration (Optional): - Optionally, you can use 'strategy-rollingUpdate.partition' to control the number of pods updated at a time. This allows you to slow down the update process by updating fewer pods at once- For example, setting 'partition' to ' 2' would update only two pods at a time.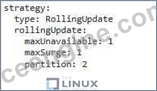
3. Create or IJpdate the Deployment: - Apply the updated YAML file using 'kubectl apply -f my-critical-service-deployment.yaml' 4. Trigger the Update: - Update the image of your application to a newer version. - You can trigger the update by pushing a new image to your container registry. 5. Monitor the Update: - Use 'kubectl get pods -I app=my-critical-service to monitor the pod updates during the rolling update process. - Observe the pods being updated one at a time, ensuring that there's always at least four replicas available. 6. Check for Successful Update: - Once the update is complete, use 'kubectl describe deployment my-critical-service' to verify that the 'updatedReplicaS field matches the 'replicas' field.,
NEW QUESTION # 35
Refer to Exhibit.
Set Configuration Context:
[student@node-1] $ | kubectl
Config use-context k8s
Context
You sometimes need to observe a pod's logs, and write those logs to a file for further analysis.
Task
Please complete the following;
* Deploy the counter pod to the cluster using the provided YAMLspec file at /opt/KDOB00201/counter.yaml
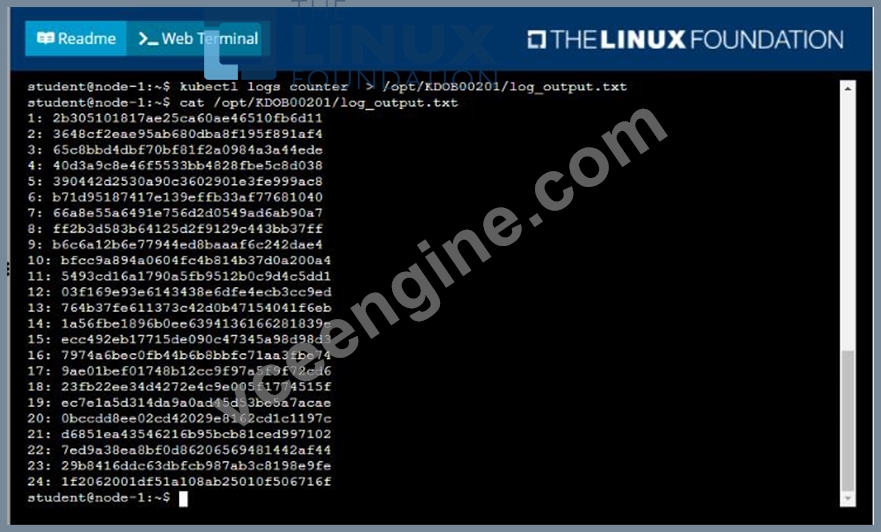
* Retrieve all currently available application logs from the running pod and store them in the file /opt/KDOB0020l/log_Output.txt, which has already been created
Answer:
Explanation:
Solution:
To deploy the counter pod to the cluster using the provided YAML spec file, you can use the kubectl apply command. The apply command creates and updates resources in a cluster.
kubectl apply -f /opt/KDOB00201/counter.yaml
This command will create the pod in the cluster. You can use the kubectl get pods command to check the status of the pod and ensure that it is running.
kubectl get pods
To retrieve all currently available application logs from the running pod and store them in the file /opt/KDOB0020l/log_Output.txt, you can use the kubectl logs command. The logs command retrieves logs from a container in a pod.
kubectl logs -f <pod-name> > /opt/KDOB0020l/log_Output.txt
Replace <pod-name> with the name of the pod.
You can also use -f option to stream the logs.
kubectl logs -f <pod-name> > /opt/KDOB0020l/log_Output.txt &
This command will retrieve the logs from the pod and write them to the /opt/KDOB0020l/log_Output.txt file.
Please note that the above command will retrieve all logs from the pod, including previous logs. If you want to retrieve only the new logs that are generated after running the command, you can add the --since flag to the kubectl logs command and specify a duration, for example --since=24h for logs generated in the last 24 hours.
Also, please note that, if the pod has multiple containers, you need to specify the container name using -c option.
kubectl logs -f <pod-name> -c <container-name> > /opt/KDOB0020l/log_Output.txt The above command will redirect the logs of the specified container to the file.

NEW QUESTION # 36
You have a Deployment named 'web-app-deployment that runs 5 replicas of a web application container. You need to ensure that only one pod iS updated at a time during a rolling update. Additionally, you want to set the update strategy so that no more than 2 pods are unavailable at any given time.
Answer:
Explanation:
See the solution below with Step by Step Explanation.
Explanation:
Solution (Step by Step) :
I). Update the Deployment YAMI-:
- Update the 'replicas' to 5.
- Define 'maxunavailable: 1 ' and 'maxSurge: 2 in the 'strategy.rollingUpdate' section to control the rolling update process.
- Configure a 'strategy.types to 'RollinglJpdate' to trigger a rolling update when the deployment is updated.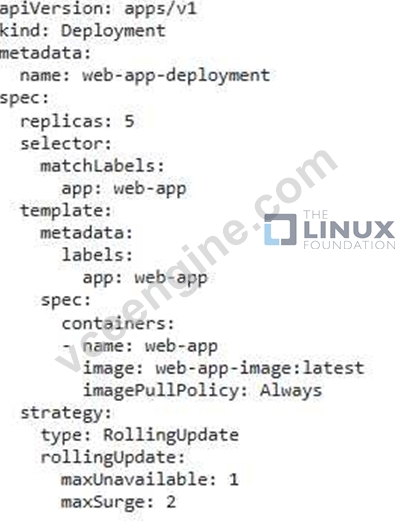
2. Create the Deployment: - Apply the updated YAML file using 'kubectl apply -f web-app-deployment-yamr 3. Verify the Deployment: - Check the status of the deployment using 'kubectl get deployments web-app-deployment to confirm the rollout and updated replica count. 4. Trigger the Automatic Update: - Push a new image to the 'web-app-image:latest' Docker Hub repository 5. Monitor the Deployment: - Use 'kubectl get pods -I app=web-app' to monitor the pod updates during the rolling update process. You will observe that one pod is terminated at a time, while one new pod with the updated image is created. Additionally, you'll see that the number of unavailable pods never exceeds 2. 6. Check for Successful Update: - Once the deployment is complete, use "oubect1 describe deployment web-app-deployment' to see that the 'updatedReplicas' field matches the 'replicas' field, indicating a successful update.
NEW QUESTION # 37
Exhibit:
Context
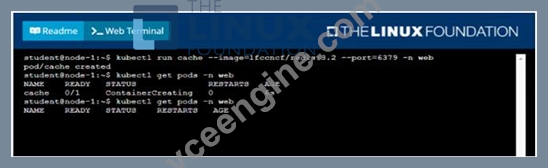
A web application requires a specific version of redis to be used as a cache.
Task
Create a pod with the following characteristics, and leave it running when complete:
* The pod must run in the web namespace.
The namespace has already been created
* The name of the pod should be cache
* Use the Ifccncf/redis image with the 3.2 tag
* Expose port 6379
- A. Solution:

- B. Solution:
Answer: A
NEW QUESTION # 38
You have a web application that requires a specific sidecar container to perform certain tasks like logging and monitoring. You need to ensure that this sidecar container iS always running alongside your application pod, even it the main application pod restarts or iS deleted and recreated. How would you achieve this using a DaemonSet in Kubernetes?
Answer:
Explanation:
See the solution below with Step by Step Explanation.
Explanation:
Solution (Step by Step) :
I). Define the DaemonSet YAML: Create a YAML file that defines the DaemonSet configuration. This file will include the following key sections:
- Metadata Includes the name and labels for the DaemonSet.
- Spec: Defines the deployment details:
- Selector: Matches the labels of the pods that the DaemonSet should manage.
- Template: Contains the pod definition:
- Containers: Defines the main application container and the sidecar container.
- Ensure the sidecar container has appropriate resources and environment variables.
- Include any necessary ports or volume mounts for the sidecar container.
- UpdateStrategy: You might want to control the update strategy (RollingUpdate or Recreate) if you have multiple nodes.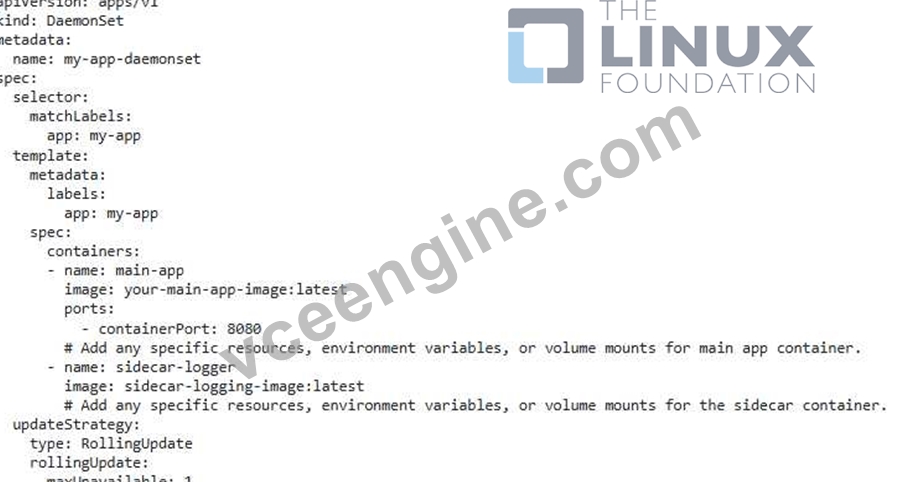
2. Create the Daemonset Apply the Daemonset YAML file to your Kubernetes cluster using 'kubectl apply -f daemonset.yamr. This will create the DaemonSet and stan deploying tne pods on each node. 3. Verify Deployment: Use 'kubectl get daemonsetS to check the status of the DaemonSet. Verify that the pods are running on each node. 4. Testing and Monitoring: - Restart or Delete the Main App Pod: Observe how the sidecar container continues running alongside the main app pod, even when the main pod is restarted or deleted and recreated. - Check Logs If your sidecar container is responsible for logging, use 'kubectl logs to check the logs from the sidecar container This approach ensures that the sidecar container remains in a ready state on each node and is always available to support your application pod, fulfilling the requirements for logging and monitoring even when the main pod restarts or is recreated.
NEW QUESTION # 39
You have a Deployment named 'wordpress-deployment' that runs 3 replicas of a Wordpress container. You need to set up resource requests and limits for CPU and memory for each pod. The application requires a minimum of 250m CPU and 512Mi memory, but it should not exceed 500m CPU and IGi memory. Furthermore, implement a resource quota for the swordpress' namespace to ensure that the total CPU requests and limits do not exceed 2 CPIJ and 4Gi memory, respectively.
Answer:
Explanation:
See the solution below with Step by Step Explanation.
Explanation:
Solution (Step by Step) :
1. Update the Deployment YAML:
- Add 'resources' to the 'containers' section, setting 'requests' and 'limits' for both CPIJ and memory.
- The 'requests' should be set to the minimum required resources, and 'limits' to the maximum allowed.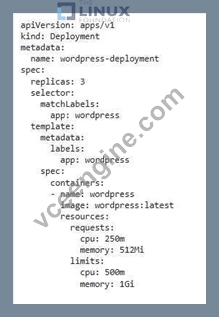
2. Create the Deployment: - Apply the updated YAML file using 'kubectl apply -f wordpress-deployment-yamr 3. Create a Resource Quota: - Create a ResourceQuota YAML file named 'wordpress-quota.yaml' with the following contents:
4. Apply the Resource Quota: - Apply the ResourceQuota YAML file using 'kubectl apply -f wordpress-quota.yamr. 5. Verify the Deployment and Quota: - Check the status of the Deployment using 'kubectl get deployments wordpress-deployment' to confirm the updated resource requests and limits. - Use ' kubectl get resourcequotas -n wordpresS to verify the applied resource quota and its remaining limits- 6. Test Resource Limits: - Try to create a new Deployment or Pod in the 'wordpress' namespace that exceeds the resource quota limits. This should result in an error, ensuring the quota is enforced.
NEW QUESTION # 40
You have a Deployment running a web application built With a Node.js container. The application currently uses an older version of the Node.js runtime, and you need to upgrade to a newer versiom Describe the steps involved in modifying the container image to include the new Node.js runtime without rebuilding the entire application.
Answer:
Explanation:
See the solution below with Step by Step Explanation.
Explanation:
Solution (Step by Step) :
1. Create a Dockerfile:
- Create a new 'Dockerfile' With the following content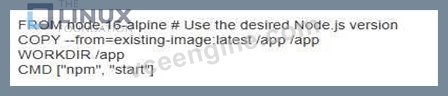
- Replace With the name of the existing Docker image used by your Deployment. - This Dockefflle uses a multi-stage build approach. It starts with a new Node.js base image and copies the application code from the existing image. This allows you to update the runtime without rebuilding the entire application. 2. Build the New Image: - Build tne image using the Dockerflle: docker build -t updated-image:latest 3. Update the Deployment - Modify your Deployment YAML file to use the newly built image:
4. Apply the Changes: - Apply the updated Deployment using 'kubectl apply -f deployment.yamr. This will trigger a rolling update to the pods using the new image. 5. Verify the Update: - Check the logs of the pods using 'kubectl logs -f ' . You should see the application running with the updated Node.js version. 6. Test the Application: - Access your application and ensure it functions correctly with the new Node.js runtime.
NEW QUESTION # 41
Context
Context
Your application's namespace requires a specific service account to be used.
Task
Update the app-a deployment in the production namespace to run as the restrictedservice service account. The service account has already been created.
Answer:
Explanation:
Solution: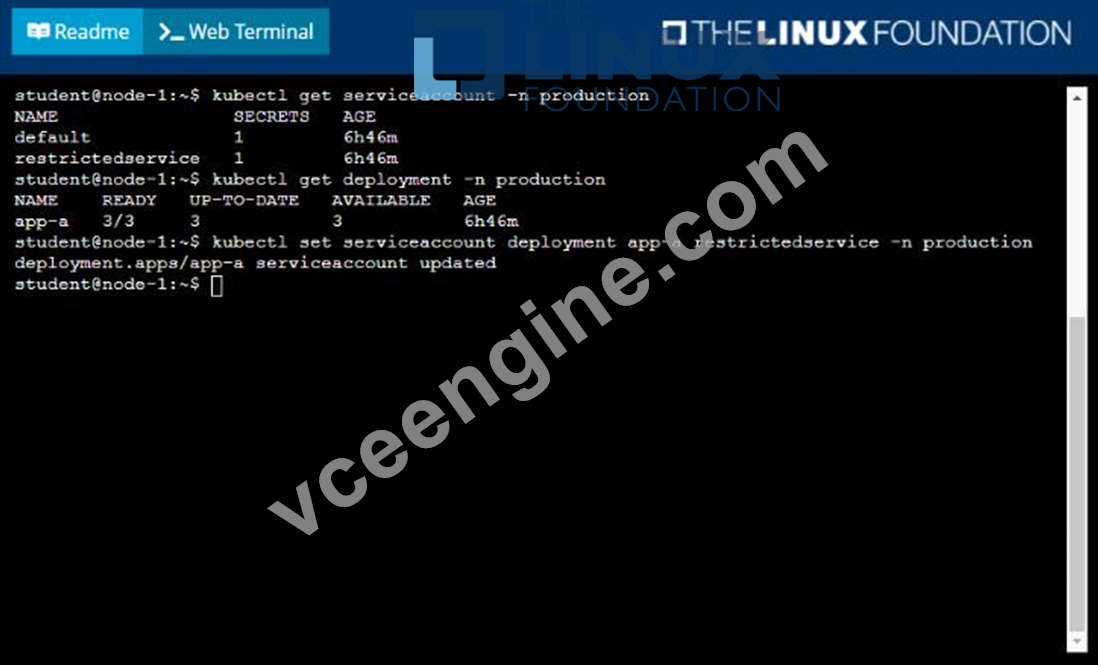
NEW QUESTION # 42
You are developing a new application that requires access to multiple services running in different namespaces. To simplify the configuration and ensure that the application can easily discover these services, you want to use a ServiceAccount with a cluster-scoped Role that grants access to services across namespaces.
Answer:
Explanation:
See the solution below with Step by Step Explanation.
Explanation:
Solution (Step by Step) :
1. Create a ClusterRole:
- Create a ClusterRole that grants access to the required services in all namespaces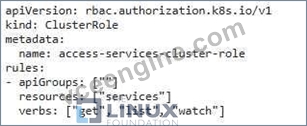
2. Create a ClusterR01e3inding: - Create a ClusterRole8inding to bind the ClusterRole to the ServiceAccount: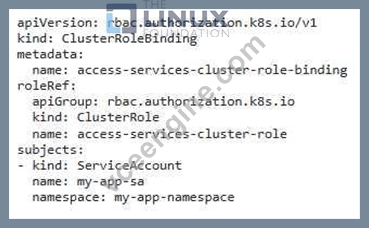
3. Create a ServiceAccount - Create a ServiceAccount in the namespace where the application is deployed:
4. Apply the Configuration: - Apply the ClusterRole, ClusterRoleBinding, and ServiceAccount using 'kL1bectl apply -f: bash kubectl apply -f access-services-cluster-role yaml kubectl apply -f access-services-cluster-role-binding.yaml kubectl apply -f my-app-sa.yaml 5. Configure the Application: - Ensure that the applications pod is using the created ServiceAccount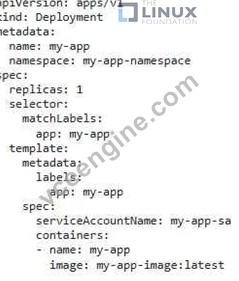
6. Test the Application: - Run the application and verify that it can successfully access the services in different namespaces. ,
NEW QUESTION # 43
You are building a new web application that utilizes a microservice architecture- One of the microservices, 'recommendation-service', is responsible for providing personalized product recommendations to users.
This service uses a machine learning model for generating recommendations based on user purchase history and browsing behavior. The model is trained offline and its weights are stored in a 'model-store' service.
Design a mufti-container Pod for the 'recommendation-service' that incorporates the following considerations:
- The Pod should include a primary container for the 'recommendation-service' application.
- The Pod should include a secondary container that runs the 'model-store' service to provide access to the trained model weights.
- Both containers should share a common volume to ensure that the model weights are available to the 'recommendation-service' container-
- The recommendation-service' snould be able to access the model weignts from the 'model-store' container witnout relying on a network call to another service-
- The recommendation-service' container should be configured to periodically update the model weights from the 'model-store' container when a new version of the model is available.
Answer:
Explanation:
See the solution below with Step by Step Explanation.
Explanation:
Solution (Step by Step) :
1. Create the Deployment YAML:
- Define a Deployment with the name 'recommendation-service'
- Set the replicas to for redundancy and scalability.
- Specify the labels Sapp: recommendation-service' for selecting the Pods in the Deployment.
- Create a 'template' section to define the Pod specificatiom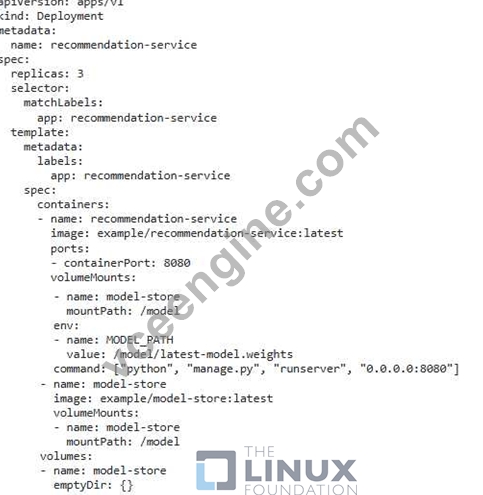
2. Deploy the Resources: - Apply the Deployment using 'kubectl apply -f deployment-yamp 3. Verify the Deployment: - Check the status of the Deployment using 'kubectl get deployments recommendation-service and ensure that three Pods are running. 4. Contigure the 'recommendation-service' - Modify the 'recommendation-service application to load the model weights from the specified path ClmodeVIatest-modeI_weightS). - Implement a mechanism within the 'recommendation-service to periodically check tor updated model weights in the shared volume. 5. Configure the 'model-store service: - Ensure that the model-store service is properly configured to store and retrieve the model weights. - Implement a mechanism in the 'model-store' service to notify the 'recommendation-service when a new model version is available. This notification can be achieved using a shared volume or a separate messaging system. 6. Test the Application: - Send requests to the 'recommendation-service' to generate recommendations. - Monitor the 'model-store' service and the shared volume to verify that the model weights are being updated correctly and the recommendation- service' is using the latest model version. Important Considerations: - Ensure that the 'recommendation-service' application is properly configured to access and load the model weights from the shared volume. - Implement a robust model management strategy, including versioning and rollback mechanisms, to ensure that the recommendation-service always uses the appropriate model. - Consider using a dedicated model store service that provides a dedicated API for retrieving and updating model weights. This can simplify the communication between the 'recommendation-service' and the model store. - Monitor the performance and resource usage of both services to ensure optimal performance.,
NEW QUESTION # 44
You are deploying a sensitive application that requires strong security measures. You need to implement a solution to prevent unauthorized access to the container's runtime environment. How would you use Seccomp profiles to enforce security policies at the container level?
Answer:
Explanation:
See the solution below with Step by Step Explanation.
Explanation:
Solution (Step by Step) :
1. Create a Seccomp Profile:
- Create a new YAML file (e.g., 'seccomp-profile.yaml') to define your Seccomp profile.
- Specify the name of the Seccomp profile and the namespace where it will be applied.
- Define the allowed syscalls for the container. You can use the 'seccomp' tool or the
'k8s.io/kubernetes/pkg/security/apparmor/seccomp' package to generate the profile.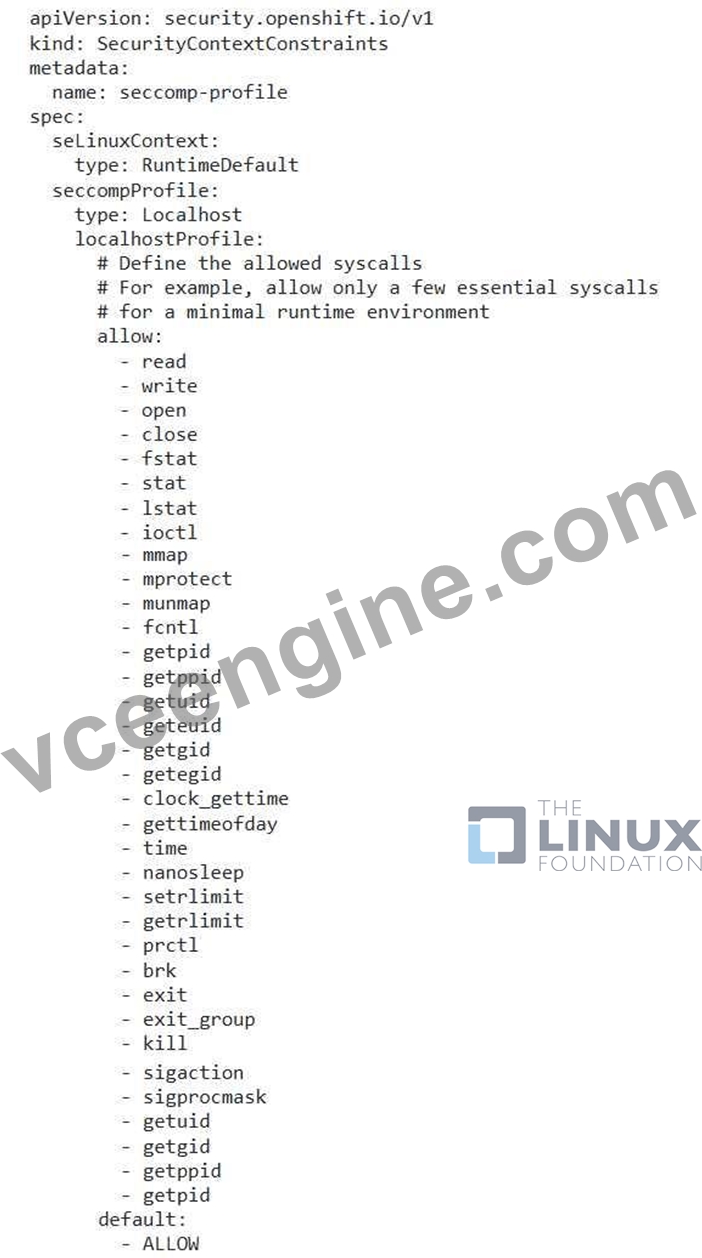
2. Apply the Seccomp Profile: - Apply the Seccomp profile to your cluster using the following command: bash kubectl apply -f seccomp-profile.yaml 3. Deploy Applications with Seccomp Profile: - Update your Deployment YAML file to include the Seccomp profile: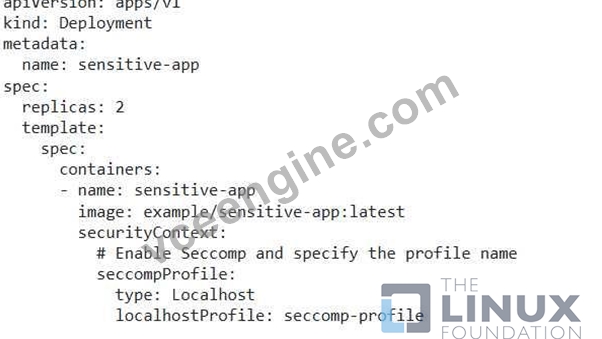
4. Verify the Seccomp Profile: - Check the status of the pods with 'kubectl describe pod - Look for the "Security Context" section and verify that the Seccomp profile is correctly applied. 5. Test the Restrictions: - Try to access system resources or make syscalls that are not allowed by your Seccomp profile. - Verify that the profile is effectively restricting the container's access to system resources.
NEW QUESTION # 45
You are developing a microservices application consisting of several deployments. One of the deployments, named 'order-service- deployments , is responsible for processing orders. Each order requires a specific backend service to process the order. You need to design a mechanism that automatically assigns an appropriate backend service to each order processing pod based on the order type. For example, orders for "books" should be assigned to the 'book-service' backend, while orders for "electronics" should be assigned to the 'electronics-service backend. Explain how you would implement this dynamic backend service assignment mechanism.
Answer:
Explanation:
See the solution below with Step by Step Explanation.
Explanation:
Solution (Step by Step) :
This scenario requires a mecnanism to dynamically assign a backend service to each order processing pod based on the order type. Here's how you can implement this:
1. Label the Backend Services:
- Label the backend services based on the order type they handle. For instance:
- 'book-service': 'order.type=books'
- 'electronics-service: 'order.type=electronics'
2. I-Ise a ConfigMap:
- Create a ConfigMap named 'order-backend-mapping' that stores the mapping between order types and backend service labels.
- Use the ConfigMap to dynamically assign backend services based on the order type.
3. Modify the Order Service Deployment: - In the 'order-service-deployment , add an init container that retrieves the backend service mapping from the ConfigMap. - Use this mapping to determine the appropriate backend service for each order. - The init container can inject environment variables or modify the pod's annotations based on the mapping.
4. Update the Order Service: - Ensure the 'order-service' container is configured to use the environment variable set by the init container to access the correct backend service. 5. Deploy the Changes: - Apply the updated ConfigMap and Deployment using 'kubectl apply' 6. Test the Dynamic Assignment: - Create orders of different types and verity that the 'order-service' pods are automatically assigned the correct backend services. ,
NEW QUESTION # 46
You have a container image for a web application that uses a specific version of a Java library_ You want to update this library to a newer version, but you are concerned about potential compatibility issues. Describe the steps involved in modifying the container image to include both the old and new versions of the library, allowing you to selectively use either version based on your needs.
Answer:
Explanation:
See the solution below with Step by Step Explanation.
Explanation:
Solution (Step by Step) :
1. Create a Dockerfile:
- Create a new 'Dockerfile' with the following content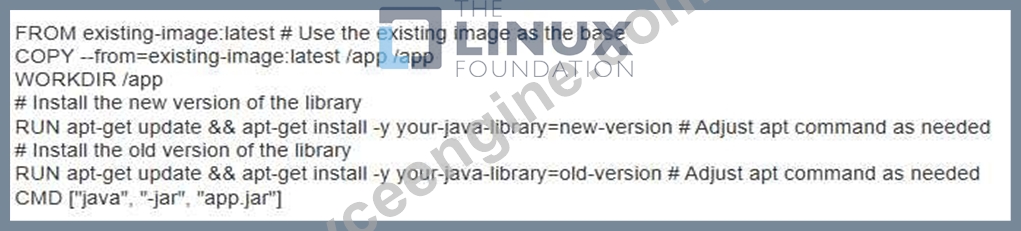
- Replace 'your-java-library' with the actual Java library name. - Replace 'new-version' and 'old-version' with the desired versions. - Adjust the 'apt-get' commands to match the package manager of your chosen base image. 2. Build the Image: - Build the image using tne Dockefflle: docker build -t updated-image:latest 3. Modify your application code: - Modify your Java code to explicitly use the desired version of the library. You can achieve this by: - Setting a System Property: Pass the desired version as a system property to the JVM, and your application can then read and use it. - Using the Classpath: Add the specific jar file for the desired version to the classpath at runtime. - Conditional Loading: Implement logic in your code to determine which version to use based on specific conditions or user input. 4. Update the Deployment: - Modify your Deployment YAML file to use the newly built image: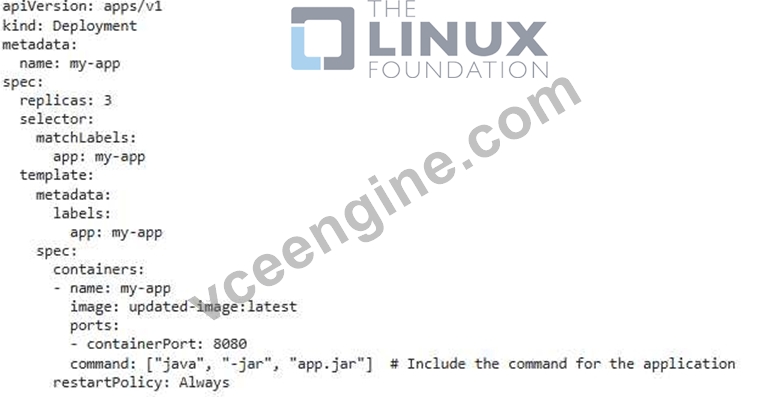
5. Apply the Changes: - Apply the updated Deployment using ' kubectl apply -f deployment_yamr 6. Test the Application: - Access your application and ensure it functions correctly with both versions of the library. You should be able to test both versions of the library and switch between them based on your requirements.,
NEW QUESTION # 47
You are deploying a microservice application consisting of three components: 'frontend' , 'backend' , and 'database'. You want to ensure that the 'backend' service is deployed only after the 'frontend' service has successfully started and is healthy. Additionally, the 'database' service should be deployed only after the 'backend' service is ready. How would you implement this deployment strategy using Kubernetes deployments?
Answer:
Explanation:
See the solution below with Step by Step Explanation.
Explanation:
Solution (Step by Step) :
1. Define Pre-requisites for Services:
- Create a 'Deployment for each service (frontend', 'backend', and 'database').
- For the 'backend' service, define a 'pre-requisite' in the 'dependencies' section of the 'Deployment' object, specifying that the ' frontend' service needs to be healthy and running. This can be achieved using the 'dependson' field in the 'spec.template.spec_containers' section of the Deployment.
- Similarly, for the 'database service, define a Tre-requisite' specifying that the 'backend' service needs to be healthy and running.
- Example 'frontend' Deployment: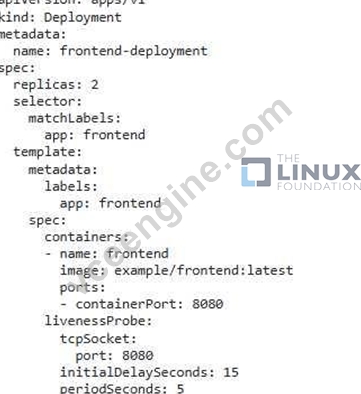
- Example 'backend' Deployment: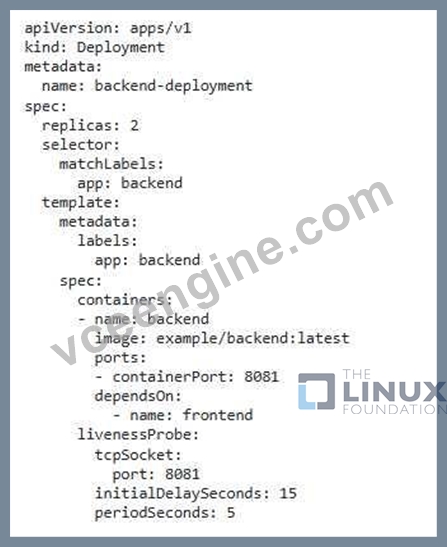
- Example 'database' Deployment: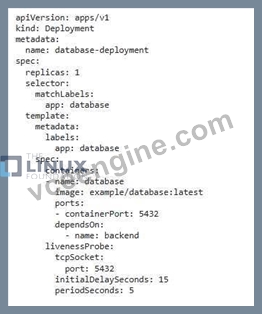
2. Create the Deployments: - Apply the YAML files using 'kubectl apply -f frontend-deployment.yamr , 'kubectl apply -f backend-deployment.yamr , and 'kubectl apply -f database- deployment-yaml. 3. Monitor the Deployment Process: - use 'kubectl get pods -l app=frontend' , 'kubectl get pods -l app=backend' , and 'kubectl get pods -l app=database' to monitor the deployment of the pods. - You will observe that the 'frontend' pods will start first, followed by the 'backend' pods after the 'frontend' pods are healthy. Finally, the 'database' pods will start after the 'backend' pods are healthy. 4. Verify the Deployment Success: - Use 'kubectl describe deployments frontend-deployment', 'kubectl describe deployments backend-deployment , and 'kubectl describe deployments database-deployment' to verify the successful deployment of each service. - Confirm that the 'Ready' status of each pod is true. This strategy ensures that the services are deployed in a predictable and reliable order, ensuring the application's integrity and functionality.,
NEW QUESTION # 48
You must connect to the correct host . Failure to do so may result in a zero score.
[candidate@base] $ ssh ckad00034c
Task
A Deployment named content-marlin-deployment , running in namespace content-marlin is exposed via Ingress content-marlin-ingress .
The manifest files for the Deployment, Service and Ingress can be found at /home/candidate/content-marlin/.
The Deployment is supposed to be reachable at
http://content-marlin.local/content-marlin , but requesting this URL is currently returning an error.
Answer:
Explanation:
See the Explanation below for complete solution.
Explanation:
ssh ckad00034c
You're debugging an Ingress # Service # Deployment chain. The fastest way is:
* reproduce the error with the right Host header
* check Ingress rules (host/path/backend)
* check Service (selector/port/targetPort)
* check Endpoints (do we have ready pods?)
* fix the manifest(s) under /home/candidate/content-marlin/
* apply + re-test
Below are the exact commands + the most common fixes for this exact symptom.
1) Reproduce the failing request correctly
Even if DNS isn't set up, you can test with a Host header:
curl -i -H "Host: content-marlin.local"
http://127.0.0.1/content-marlin
If your ingress controller is not on localhost, find the NodePort/LoadBalancer IP. In these labs it's often localhost via a local proxy, but if needed:
kubectl get svc -A | egrep -i 'ingress|nginx'
kubectl get nodes -o wide
(But start with the localhost curl above.)
2) Inspect the provided manifests (this is what you must edit)
cd /home/candidate/content-marlin/
ls -l
sed -n '1,200p' *.yaml
Also view what's currently live in the cluster:
kubectl -n content-marlin get deploy,svc,ingress
kubectl -n content-marlin describe ingress content-marlin-ingress
kubectl -n content-marlin get ingress content-marlin-ingress -o yaml
What to look for in the Ingress:
* spec.rules.host should be content-marlin.local
* spec.rules.http.paths[].path should match /content-marlin
* Backend service name must be your service
* Backend service port must match the service port (name or number)
* pathType should be Prefix (usually safest)
3) Validate Service # Pod wiring (most common real cause)
3.1 Check service selector and ports
kubectl -n content-marlin get svc -o wide
kubectl -n content-marlin describe svc content-marlin-deployment 2>/dev/null || true kubectl -n content-marlin describe svc Identify the service that the Ingress points to (from describe ingress).
Check if the Service selector matches pod labels:
kubectl -n content-marlin get pods --show-labels
kubectl -n content-marlin get svc <SERVICE_NAME> -o jsonpath='{.spec.selector}{"\n"}'
3.2 Check endpoints (this tells you instantly if traffic can reach pods) kubectl -n content-marlin get endpoints kubectl -n content-marlin get endpoints <SERVICE_NAME> -o wide
* If ENDPOINTS is empty # Service selector doesn't match Pods OR Pods aren't Ready.
3.3 If endpoints empty, check pod readiness and labels
kubectl -n content-marlin get pods -o wide
kubectl -n content-marlin describe pod <pod-name>
4) Apply the most likely fix patterns
Fix pattern A: Ingress path needs rewrite
If your app serves / but you route /content-marlin, you often need rewrite.
Edit content-marlin-ingress manifest (in /home/candidate/content-marlin/) to include:
* path: /content-marlin
* pathType: Prefix
* annotation: rewrite to / (common for nginx ingress)
Example (typical nginx-ingress):
metadata:
annotations:
nginx.ingress.kubernetes.io/rewrite-target: /
spec:
rules:
- host: content-marlin.local
http:
paths:
- path: /content-marlin
pathType: Prefix
backend:
service:
name: <SERVICE_NAME>
port:
number: 80
If your ingress controller is not nginx, rewrite annotation may differ. But in CKAD labs, it's very often nginx.
Fix pattern B: Ingress points to wrong Service port
If the Ingress backend says port 80 but your Service exposes 8080 (or uses a named port), align them:
* Either change Ingress backend port.number
* Or change Service spec.ports[].port / targetPort
Fix pattern C: Service selector mismatch (endpoints empty)
If pods have label app=content-marlin but service selector is app=content-marlin-deployment (or vice versa), fix the Service selector to match pod labels.
Service should have:
spec:
selector:
app: <label-that-actually-exists-on-pods>
Fix pattern D: Service targetPort wrong
If container listens on 8080 but service targetPort is 80, fix it:
spec:
ports:
- port: 80
targetPort: 8080
5) Apply the corrected manifests
After editing the YAMLs under /home/candidate/content-marlin/:
kubectl apply -f /home/candidate/content-marlin/
Wait for readiness:
kubectl -n content-marlin rollout status deploy content-marlin-deployment kubectl -n content-marlin get endpoints kubectl -n content-marlin describe ingress content-marlin-ingress
6) Re-test the URL
curl -i -H "Host: content-marlin.local"
http://127.0.0.1/content-marlin
If you still get errors, also check ingress controller logs/events quickly:
kubectl -n content-marlin get events --sort-by=.lastTimestamp | tail -n 30 kubectl get pods -A | egrep -i 'ingress|nginx' The fastest way for you to finish in 1 shot Run these and paste the output (I'll tell you exactly which line to change and what to change it to):
kubectl -n content-marlin describe ingress content-marlin-ingress
kubectl -n content-marlin get svc -o wide
kubectl -n content-marlin get endpoints -o wide
kubectl -n content-marlin get pods --show-labels
sed -n '1,200p' /home/candidate/content-marlin/*.yaml
But even without pasting, if you follow steps 2-4 above, you'll find the broken link (Ingress rule, Service port, selector, or rewrite) and fix it cleanly.
NEW QUESTION # 49
......
The CKAD certification exam is a rigorous test that evaluates the candidate’s ability to work with Kubernetes to deploy and manage containerized applications. Candidates are expected to have a good understanding of Kubernetes concepts and be able to use Kubernetes to solve real-world problems. CKAD exam consists of a series of performance-based tasks that require the candidate to complete various Kubernetes-related challenges, such as deploying a multi-container application, configuring a Kubernetes cluster, creating and deploying a service, and troubleshooting a Kubernetes cluster. CKAD exam is proctored, and candidates are required to demonstrate their skills in a real-world environment. Upon completion of the exam, candidates receive a CKAD certification, which is recognized by organizations worldwide as a symbol of expertise in Kubernetes application development.
Practice LATEST CKAD Exam Updated 239 Questions: https://actualtests.vceengine.com/CKAD-vce-test-engine.html
